How OpenClaw stores data is easiest to understand when you look at where the agent actually runs. In a managed setup, the important question is not just whether data is saved, but which environment holds it and who can reach it.
If you are using OpenClaw now, you probably want a clear answer to two things: what stays private, and what happens when an agent reads, writes, or remembers something. That matters even more when you are handling workflows, files, or business data that should not leak into a shared system.
This article focuses on hosted private-cloud storage, not local-device memory. That means we are looking at how data lives inside an isolated agent environment, how access is limited, and where this model is strong enough for real work.
By the end, you will have a practical picture of what OpenClaw stores, what isolation changes, and when a managed instance is the safer choice for your workflow.
Each agent runs in its own isolated environment
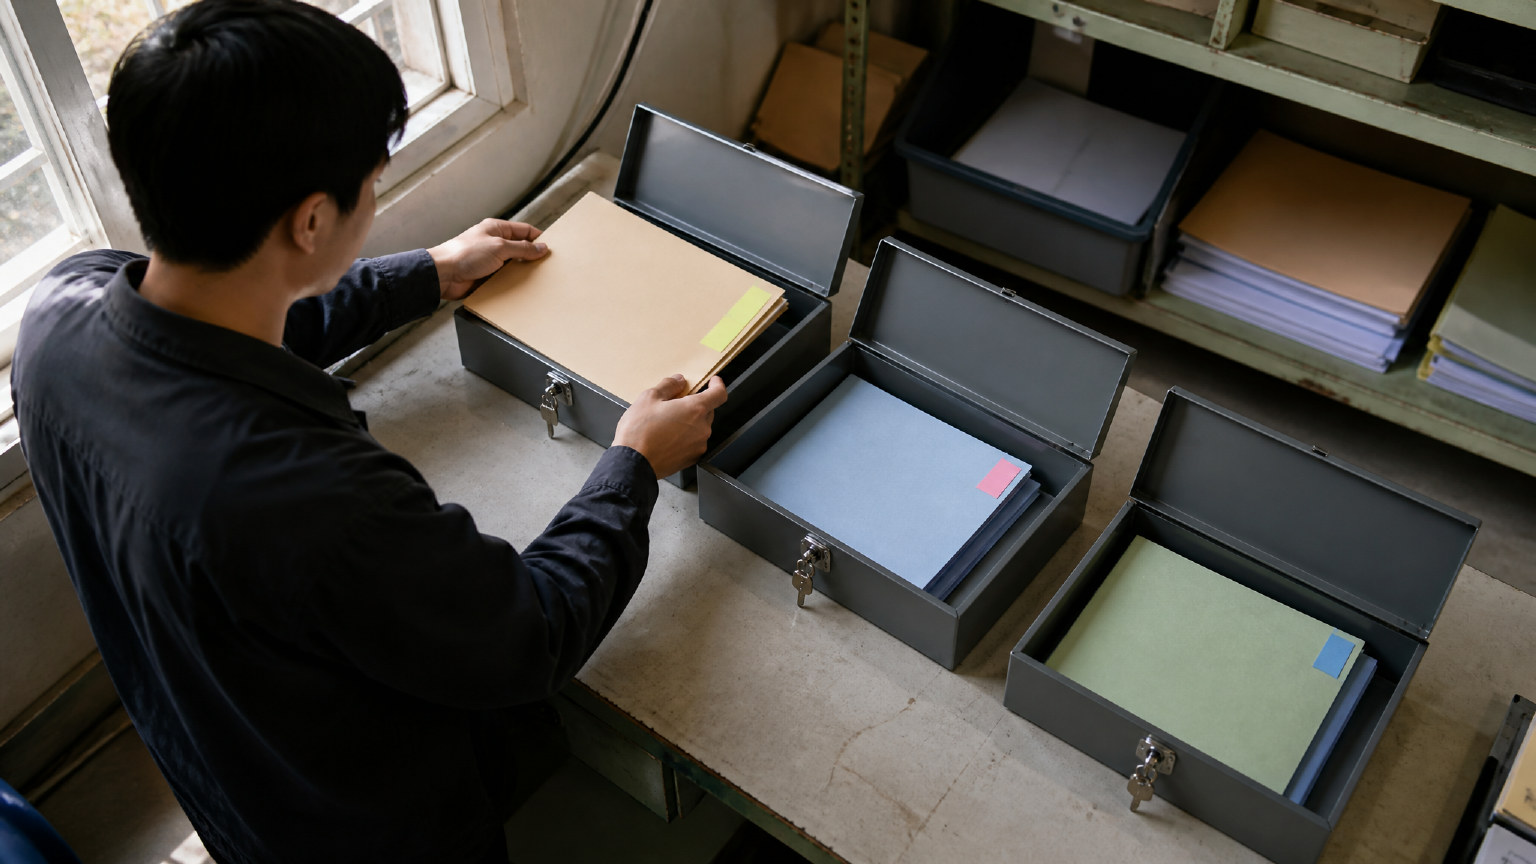
OpenClaw keeps each agent inside a separate environment, so its files, memory, and runtime state do not sit in a shared workspace with other agents. For you, that means one agent can work on a CSV cleanup, another can draft content, and a third can handle a Telegram workflow without mixing their working data together.
This isolation matters because agent data is not just one thing. It can include prompts, task context, generated outputs, cached files, and the small pieces of state that help an agent continue a workflow after a pause. When those pieces live in one shared place, it is easier for one task to overwrite another or for a later update to pull in the wrong context. In a managed private-cloud setup, the point is to keep those boundaries clear from the start.
In practice, isolation changes access in a simple way: an agent can work with what belongs to that environment, but it does not automatically see data from other agents or other instances. That reduces accidental cross-talk between workflows and makes it easier to reason about where a result came from. It also helps when you are using OpenClaw for different clients, teams, or projects that should stay separated.
That said, isolation is not the same as a complete data policy. It does not replace good decisions about what you store, who can log in, or whether a task should touch sensitive material at all. If a workflow needs broader access, shared records, or long-term governance across systems, you still need to plan for that outside the agent environment. Isolation gives you a cleaner boundary; it does not solve every storage or compliance question by itself.
For most builders, the practical benefit is less debugging and fewer surprises. You are not chasing version conflicts, stray files, or a single workspace that has grown messy over time. Each agent gets its own place to operate, so the data it uses stays tied to that agent’s job instead of bleeding into everything else.
What data stays inside the private cloud
How OpenClaw stores data in TryOpenClaw comes down to a simple rule: the agent’s working data stays inside its own private-cloud environment, not on a shared system that other users can touch. That includes the files, notes, workflow state, and other agent-specific material needed for the job you assigned.
In practice, this means the data tied to one agent remains scoped to that agent’s instance. You are not depending on a common workspace where unrelated projects, updates, or users can mix together. For people who care about privacy and operational clarity, that separation is the main point.
The useful way to think about it is not “does OpenClaw remember things?” but “where does that memory live?” In this setup, the answer is the private cloud environment created for your agent. That environment is where the agent’s data lives while it is being used, so the storage model is built around isolation rather than a shared pool.
This matters because it reduces accidental exposure between workflows. If you are using OpenClaw for research, content production, Telegram or Discord management, or CSV and Excel analysis, the data for one task should remain inside the environment that task uses. That keeps the working context focused and easier to reason about.
Not every kind of information belongs there in the same way. The private cloud is meant for agent data that supports execution: inputs, outputs, intermediate state, and the files or references the agent needs while working. It is not a vague promise that all information everywhere disappears; it is a defined boundary for the agent’s own storage and access.
That boundary is also what makes the setup easier to trust in day-to-day use. You know where the data lives, who can reach it, and which agent it belongs to. For a hosted service, that clarity is often more valuable than trying to manage storage yourself across local machines and ad hoc folders.
There is still an important limit to understand: isolation helps, but it does not replace good data discipline. If you give an agent access to sensitive sources, external services, or shared team content, the private-cloud boundary does not make those sources disappear. It simply keeps the agent’s own environment separate from other agents and other customer environments.
So the right question is not whether the private cloud is magical. It is whether the storage model matches the way you work. If you want OpenClaw running in a dedicated environment with data kept inside that boundary, this is the model that supports that goal.
How storage behaves when you log in and assign work
When you log in and assign work, the data stays tied to that OpenClaw instance, not to your local device. In a managed setup like TryOpenClaw, the practical effect is simple: you open the environment, hand tasks to an agent, and the workspace keeps the files, context, and outputs needed for that work inside the same private boundary.
That matters because storage is not just about where a file is saved once. It also affects what the agent can read again on the next run, what it can reuse during a workflow, and what another environment cannot see. If you upload a CSV, draft copy, or a working document, the agent can act on it inside that instance without forcing you to rebuild the setup every time you return.
In practice, the sequence looks like this: you sign in, the instance is already available, and you assign a task. From there, storage behaves like a persistent workspace for that agent, so the work does not depend on your laptop session staying open. That is useful for automation jobs that move across steps, such as analysis, content generation, or repeated updates to the same project files.
It also changes how you think about access. The agent can use the data needed for the job, but the point of the private-cloud model is that this data is not spread across unrelated systems. For a team or builder, that reduces the risk of mixing one workflow’s inputs with another workflow’s outputs. If you want a broader view of the service model behind that behavior, the managed OpenClaw instance explains how the environment is provisioned and reused.
This setup is not enough if you need the agent to reach outside the instance on its own. For example, if your process depends on external systems, shared corporate storage, or data that must be synchronized across tools, you still need to plan those connections deliberately. The private environment protects the boundary; it does not replace integration design, retention policy, or access control on the systems around it.
How TryOpenClaw avoids the setup problems that break data workflows
TryOpenClaw avoids those setup problems by giving you a ready OpenClaw instance in a private cloud, so data work starts inside a controlled environment instead of on a half-configured local machine. That matters when the workflow depends on CSV files, spreadsheets, API-driven tasks, or repeated agent runs that should behave the same way every time.
With a managed instance, you do not need to clone a repo, start Docker, resolve port conflicts, or chase dependency mismatches before the agent can do useful work. The practical result is simpler: you sign in, assign the task, and keep the data path inside the same isolated environment from the first run onward.
Những điểm chính
- The main benefit is operational: fewer setup steps means fewer places for data workflows to fail before they begin.
- Because the instance is already running, the agent can work inside a stable environment instead of depending on your local device state.
- Isolation helps keep one agent’s files and activity separate from other instances, which is useful when you handle sensitive or client-specific work.
- This model reduces version drift, port issues, and dependency conflicts that often break automation after updates.
- It is still not a substitute for external integration design when your workflow must connect to other systems or share data across tools.
The setup difference also changes how you think about reliability. In a local-first workflow, data can be fine one day and broken the next because the environment changed under it. In TryOpenClaw, the storage and execution context live together in the hosted instance, so the agent is less exposed to machine-specific problems like missing libraries, stale containers, or a port already in use.
That is especially helpful for workflows that touch files repeatedly. If an agent is parsing spreadsheets, preparing reports, or running a sequence of automation steps, the value is not just that the data is stored somewhere private. The value is that the same private environment is also where the agent operates, which lowers the chance of silent breakage between storage, execution, and update cycles.
There is also a security and access side to the setup story. Isolation means you are not relying on a shared runtime where another project’s state can interfere with yours. It does not remove the need for good permissions on connected systems, but it does keep the OpenClaw side of the workflow contained, which is the part most users want clarified when they ask where their data lives.
So the short answer is this: TryOpenClaw reduces setup risk by moving OpenClaw into a managed private-cloud instance where the environment is already prepared for agent work. That makes data workflows easier to start, easier to repeat, and less likely to fail because of local configuration problems.
If your process still depends on outside systems, shared storage, or cross-tool synchronization, you will need to handle those connections separately. The managed instance keeps the OpenClaw boundary stable; it does not replace the design of everything around it.
When this storage model is the right fit
This setup fits best when you want OpenClaw to keep agent data inside a managed private environment, without spending time on infrastructure. It is a practical choice for developers, builders, and teams that need to start using agents quickly, but still want a clear boundary around where work files, memory, and workflow outputs live.
It is especially useful when you care about privacy by design, repeatable access, and fewer moving parts. Instead of treating storage as something you assemble yourself, you get a hosted instance that is already ready for login, task assignment, and ongoing automation.
The model also makes sense when your use case is operational, not experimental. If you are parsing CSV or Excel files, running research tasks, managing Telegram or Discord workflows, or generating content with agents, a managed instance gives you a stable place for that work to happen. You are not depending on a local machine staying on, a repo staying in sync, or a Docker setup staying healthy after every change.
For many users, that stability matters more than maximum control. You still need to decide what data should be sent to external services, but the OpenClaw side of the boundary stays isolated and predictable.
This is also the right fit when your team needs a shared operating model without shared data. Each agent runs in its own environment, so one workflow does not bleed into another by default. That helps when you want to separate clients, projects, or internal tasks while keeping the same OpenClaw experience across them.
It is less suitable if your process depends on a fully custom stack, deep system-level integrations, or storage rules that must be controlled at the machine level. In those cases, managed storage can still be the right starting point, but it will not replace the design decisions of the tools around it.
In short, choose this model when you want the benefits of hosted OpenClaw storage without taking on the cost of running it yourself. You get isolation, faster setup, and a clearer privacy boundary, while keeping the option to build more around it as your workflow grows.
What to check before you start using a managed OpenClaw instance
Before you start, check what the instance is meant to store, who can access it, and whether your workflow needs any extra controls. A managed OpenClaw instance gives you a private environment, but the privacy boundary still depends on how you use it and what you connect to it. If you know that upfront, you can avoid surprises later.
First, separate the kinds of data you plan to place there. Agent memory, uploaded files, task outputs, and workflow notes may all live in the same environment, but they do not all deserve the same treatment. If a task involves sensitive customer data, internal documents, or credentials, make sure that content is actually appropriate for a hosted setup before you send it in.
Next, confirm the access model. In a managed instance, the main question is not whether the data is on your laptop; it is whether the right people can reach the instance, the workspace, and any connected services. Review who has login access, whether shared accounts are allowed, and whether your team needs separate permissions for different agents or projects.
It also helps to check the external dependencies around the instance. Even when OpenClaw data stays isolated inside its own environment, an agent may still interact with APIs, storage services, spreadsheets, or chat platforms. Each integration creates another place where data can leave the private cloud, so only connect what the workflow truly needs.
Finally, decide what “enough privacy” means for your use case. A managed OpenClaw instance is a strong fit when you want hosted isolation and fast setup, but it is not the right answer for every workload. If your process requires strict on-premises control, custom compliance rules, or full ownership of the underlying infrastructure, you should evaluate whether a private hosted environment is sufficient or whether you need something more controlled.
The practical test is simple: if the data can live in an isolated agent environment, and the connected tools are limited to what your workflow needs, a managed instance is usually enough. If not, treat it as a starting point and plan the extra controls before you put important data into production.
Related Posts
Cách chạy workflow tự động hóa 24/7 trên cloud cho doanh nghiệp
Cách dùng OpenClaw tìm và sửa lỗi code tự động cho dự án